

Update, 3 October 2026. The experiment below was published on 3 April. The 35B model was Qwen3.5-35B-A3B; Gemma replaced the smaller classification and summarization models. The measurements belong to those April runs.
Running a local LLM on a 16GB Mac Mini: what changed
The setup changed after this article. My project notes record a warm-cache comparison on 23 April: Qwen3.5 4B classified 8 of 10 prompts correctly at an average 0.89 seconds; Gemma 4 E2B classified 7 of 10 at 0.84 seconds. That small test favored keeping Qwen for this particular job. One answer changes the accuracy by ten percentage points, so I would be careful about generalizing it.
The project configuration now uses Qwen3.5 4B and 9B through Ollama. The separate llama.cpp 35B server was later retired; its removal was verified in the project notes by 22 July. Local inference is reserved for utility tasks such as classification and summarization. The old local-agent fallback chain below describes the April setup.
I have not rerun the 35B experiment for this update. The original 17.3 tokens per second is a recorded result from that setup. It should not be read as a speed guarantee for another Mac, a different quantization, or today's software.
Qwen 35B and Gemma 4 were different parts of the experiment
Heavy tier in April: Qwen3.5-35B-A3B, using the UD-IQ3_XXS GGUF in llama.cpp. The article reported 17.3 tokens per second.
Smaller tiers after the April 2 swap: Gemma 4 E2B for classification and E4B for summarization in Ollama.
Original classification comparison: 8.5 seconds with the smaller Qwen setup versus 1.9 seconds with Gemma. The later warm-cache comparison above is a separate test and should stay separate.
Current project configuration: Qwen3.5 4B and 9B through Ollama. The retired 35B service is no longer the production setup.
For the hardware move itself, the headless Mac Mini migration article gives the surrounding context. The sections that follow preserve the April experiment, with corrections to the memory explanation and setup guidance.
The original April 3 experiment
A few weeks ago I wrote about running Qwen on my MacBook and iPhone. That was the first experiment. Local models doing real work on normal hardware. The gap between local and cloud was closing fast, and I wanted to push it further.
So I did. I moved everything to a headless Mac Mini M4, the base $599 model with 16GB of RAM. Started with smaller Qwen models for message classification and context compression. Then I found a way to run a 35 billion parameter model on 16 gigs. 17 tokens per second. Zero swap. Everyone said you need 32GB minimum. I’ve been running it for about a week now.
Yesterday Google dropped Gemma 4 under Apache 2.0. Within hours I benchmarked it against my Qwen setup. Classification went from 8.5 seconds to 1.9 seconds. By evening the swap was done. Five files changed.
This is all of it. How I fit a 35B model on a $600 machine, what local models actually do when you’re running an AI agent 24/7 (spoiler: it’s way more than classification), how model routing works across three tiers, and why Gemma 4 made me swap the brain overnight.

Why I Needed Local AI (It’s More Than You’d Think)
My Mac Mini runs as a headless AI automation server. iMessages, emails, scheduled nightshift tasks, 35+ specialized skills. The brain is Claude Code. Claude is brilliant. Claude also has usage limits.
I pay for Claude Max. It’s not cheap. And every wake-up burns through that subscription. I needed a way to handle the routine work locally. Free. On the machine itself.
At first I thought this would just be message classification. Is this a question or a greeting? Route the boring stuff away from Claude. That’s how it started.
Turns out that was maybe 20% of what local models can do. Here’s what actually runs locally now:
Message triage: classifying every incoming message (question, request, idea, greeting, FYI) and assessing urgency. Under 2 seconds per message.
Context compression: when someone sends a 500-word message, the local model compresses it to 30 words before Claude sees it. Same understanding, fewer tokens.
Signal compression: my agent collects signals all day long (errors, metrics, task outcomes, all kinds of stuff). Before the nightshift planning session, the 35B compresses the entire day into a dense summary. Saves roughly 15x in tokens for the Opus planning call. That’s a lot of money over a month.
Email preprocessing: same triage pattern applied to incoming emails before deciding whether to spin up a full Claude session.
Memory consolidation: the agent accumulates daily notes and context. A local model clusters related entries and merges them. Like defragmenting a hard drive, but for the agent’s memory.
Fallback: when Claude is rate-limited or down at 3am, the local 35B handles operational tasks. Not Claude-level reasoning, but functional.
The triage classification is just one example. The local models touch nearly everything the agent does. The result: roughly 30-40% fewer Claude sessions compared to routing everything through the API. My subscription lasts longer. And the agent responds faster for routine work because there’s no network round-trip.
Three Tiers, One $600 Machine
Not every task needs the same model. Like, classifying “is this a question or just ok?” is a completely different thing than compressing an entire day of automation signals into a planning summary. So I built a routing system. Three local tiers plus the cloud.
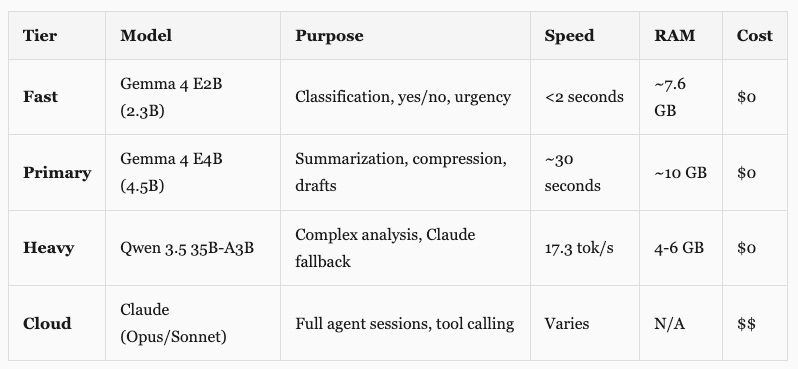
Why three tiers and not just one? A 2B model can tell you whether “What’s the status?” is a question or a greeting. But it can’t produce a useful 30-word summary of a 500-word message. And neither the 2B nor the 4.5B can do what the 35B does: compress an entire day of signals into a dense planning brief, or serve as a real fallback when Claude goes down. Different tools for different jobs.
The fast tier runs on every incoming message. Classifies the type (question, request, idea, greeting, FYI), assesses urgency. Under 2 seconds. If the message is a greeting or pure FYI, the agent skips Claude entirely. This one needs to be fast because it runs on every single message, all day.
The primary tier handles tasks where you need actual language understanding. Context compression is the main one: someone sends a long message, this model condenses it to 30 words before Claude sees it. It also handles things like Substack Notes generation as a fallback and the morning report AI summary. The 2.3B fast model can’t produce quality summaries. The 35B is overkill for this. The 4.5B sits in the sweet spot.
The heavy tier is where it gets interesting. The 35B does two things. It handles complex preprocessing (compressing the day’s automation signals before the nightshift Opus planning call, which saves roughly 15x in tokens). And it sits in the resilience chain as a Claude fallback. When Claude is rate-limited at 4am, the 35B handles health checks, error scanning, operational maintenance. Always marked as “[Local Fallback]” so I see the difference in the morning. But something functional beats nothing at 3am.
The triage routing for messages looks like this:
1. Incoming message hits triage
2. Fast tier classifies (question/request/idea/greeting/fyi) + urgency
3. If greeting or fyi: skip Claude entirely
4. If long text: primary or heavy tier summarizes before Claude sees it
5. Prepend classification to Claude's prompt: "[Pre-classified: request, urgency: high]"
6. Claude skips its own analysis step = fewer tokens burned
But message triage is just the entry point. The same models handle signal compression, email preprocessing, memory consolidation, fallback responses. The routing system is the foundation. The use cases keep growing, and that’s kind of the point.
Safety rules still matter. Messages mentioning money, deployment, publishing, or anything work-related always bypass local triage and go straight to Claude. Very short messages (under 20 characters) also skip triage because “yes” could be a standalone acknowledgment or an answer to a previous question. I learned that one the hard way when the triage classified “yes” as acknowledgment and skipped a real conversation reply.
The 35B Trick (Your SSD Is the New GPU Memory)
This is the part that shouldn’t work. I didn’t invent this. I came across a post on X where someone was running oversized models on consumer hardware using a specific flag in llama.cpp. That sent me down a rabbit hole.
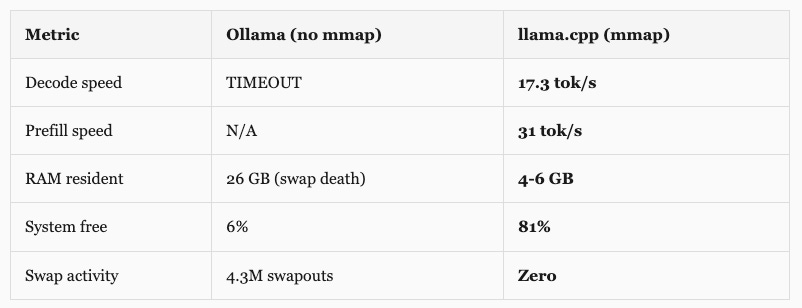
Qwen 3.5 35B-A3B has 35 billion parameters. At standard precision, that’s way more than 16GB. My first attempt through Ollama loaded 26GB into memory on a 16GB machine. The system froze. 4.3 million swapouts. Timed out after 10 minutes without producing a single token. Dead.
Then I tried llama.cpp with one flag: --mmap.
Same model. Same hardware. Same 16GB. Result: 17.3 tokens per second, 81% memory free, zero swap.
What mmap explains, and what it does not
Qwen's model card describes 35 billion total parameters with 3 billion active per token. That reduces the computation needed for each token. Different tokens can use different experts, so the active parameter count alone does not determine how much memory a run needs.
Memory mapping gives the operating system a file-backed view of the model weights. Pages can be read as needed and cached in RAM. Model quantization, context length, runtime buffers, and other processes still affect memory pressure. Zero swap in a reported run does not establish that inference involved no disk reads, or that most of the model remained untouched.
The current llama.cpp server documentation lists loading modes, including memory mapping. Its default auto mode uses mmap when supported. The old command in this article used --mmap; check the installed version's help before copying flags from an older experiment.
Apple's LLM in a Flash research is relevant background on inference with limited memory and flash storage. It does not validate this Mac Mini run or show that one llama.cpp flag reproduces the paper's method.
My original article reported 17.3 tokens per second for the quantized 35B model and 12.6 for the earlier 9B setup. I am retaining those as historical observations. The article did not provide enough of the run record to isolate mmap as the cause of the difference.
The downloaded model was the aggressively quantized UD-IQ3_XXS version, reported as about 13GB on disk. Quantization is part of the result. Comparing a different model file or precision would be a different experiment.
The Brain Swap (Qwen to Gemma)
For about a week, everything ran on Qwen 3.5 across all tiers. It worked. Classification took about 8-9 seconds on the 4B model, summarization around 50 seconds on the 9B. Not blazing, but good enough for background preprocessing that doesn’t need instant responses. The system was stable. I was happy with it.
Then yesterday, Google released Gemma 4.
Google's model card lists Gemma 4 under Apache 2.0. That was useful for the setup I was building. The license still has conditions, and support for a model's capabilities depends on the inference software as well as the model.
The small Gemma models also made multimodal input worth investigating. Google's model overview lists the supported inputs by variant. My classification and summarization tests below used text; they do not establish that image or audio processing worked in my message-routing system.
I wasn’t going to swap production models based on a marketing page though. Wrote a benchmark script, ran 10 classification prompts and 3 summarization tasks against each model under identical conditions.
Classification (10 test messages)

Summarization (3 test texts)

4.4x faster classification. 1.8x faster summarization. The speed difference is what sold me. For a triage system that runs on every incoming message, 1.9 seconds vs 8.5 seconds is the difference between “barely noticeable” and “why is this taking so long.”
The accuracy gap (70% vs 80%) turned out to be mostly gray areas. Both models classified “What’s the status of the nightshift?” as status_check instead of question. Honestly, status_check is a better answer. One genuine miss: Gemma said “observation” for a message where “fyi” would’ve been correct. It invented a category that wasn’t in the allowed list. Edge case I can fix with better prompting.
The actual swap was anticlimactic. My architecture centralizes model names in one file. Two constants changed, three files with hardcoded model strings updated. Done.
# automation/lib/local_llm.py
MODEL_PRIMARY = "gemma4:e4b"   # was "qwen3.5:9b"
MODEL_FAST = "gemma4:e2b"      # was "qwen3.5:4b"
The heavy tier stays on Qwen 35B via llama.cpp. Deliberately. The fast and primary tiers run through Ollama, which had Gemma 4 support on day one (I upgraded Ollama from 0.19 to 0.20 for it). The heavy tier runs through llama.cpp with the mmap trick. Swapping that to Gemma’s 26B MoE variant means testing a different quantization, different mmap behavior, different inference characteristics. I don’t change two things at once in production infrastructure. Qwen 35B works. It stays until I’ve properly benchmarked the Gemma 26B alternative.
Old Qwen models stay on disk as rollback. If anything breaks, reverting the fast and primary tiers is a two-line change.
Thinking controls and context length
The April experiment reported that disabling thinking cut a simple classification task from more than 30 seconds to under a second. That was one workload. The earlier description made the control sound universal across models.
Ollama's current documentation says thinking controls vary by model. Its /api/show response can describe the supported values; think: false requests no thinking output where the model permits it. Check the response for the model actually installed.
Context length also belongs in the test record. The original setup used different limits for classification, summarization, and the heavy tier. Ollama's FAQ explains that context and parallel requests affect memory use. Start with the context the task needs, then measure the complete request time and answer quality before increasing it.
The April fallback chain, since retired
This section records the old design. In the current project, local models handle utility work; they are no longer the fallback agent runtime described here.
The local models aren’t just about cost. They’re about uptime.
My agent’s resilience chain works like a waterfall. If the top tier fails, it cascades down:
Claude Sonnet -> retry -> Haiku -> Local 35B -> Local Primary -> OpenRouter -> QueueLike backup generators. Main power (Claude Sonnet) goes out. Building tries the secondary generator (Haiku). If that’s down too, local generators kick in. Not as powerful, but they’re on-site, zero-cost, and they don’t depend on anyone else’s infrastructure staying online. Only if everything local fails does the system reach for an external API (OpenRouter). And if even that fails, the message goes into a queue for later.
The system tracks cooldowns per model too. If Claude hits a rate limit, it records how long to wait and skips straight to the next tier on subsequent requests. No point retrying something you know will fail. Once the OAuth token expired at 2am and the system figured out that all Claude tiers would fail with the same expired token, so it skipped straight to the local fallback. Saved minutes of retries that were guaranteed to fail. I only found out in the morning when I read the logs. It just handled it.
My agent runs overnight. Nightshift tasks execute while I sleep. If Claude is rate-limited at 4am, the local 35B handles operational checks, health monitoring, error registry scans. Responses are clearly marked “[Local Fallback]” so I see the difference in the morning. Not Claude-level reasoning, but functional. And I’d rather wake up to a degraded response than a silent failure.
Before trying this on another Mac
The original machine was a base M4 Mac Mini with 16GB unified memory, bought at the $599 base price. This experiment does not establish the same performance on every 16GB Apple Silicon Mac.
For a first local test, I would begin with one smaller model and one task. Record the model tag and quantization, runtime version, context size, and whether the model was already loaded. Then separate the time spent loading and processing the prompt from the time spent generating the answer. A fast decode rate can still hide a slow request.
For the larger-model experiment, the missing details matter more. The published article does not include a pinned llama.cpp revision and GGUF checksum alongside raw logs for the 17.3 tokens-per-second result. I am keeping the result in the historical account and removing the old copy-and-run recipe until those reproduction details are available.
One correction to that recipe: setting GPU layers to zero selects CPU execution for those layers. Shared memory does not make CPU and GPU execution equivalent. Loading mode and device placement are separate settings in the llama.cpp server options.
For Ollama, the memory and concurrency settings control how many models and requests can stay active. Environment variables need to reach the running server process. Exporting them in a new terminal does not reconfigure an already-running background service.
What I kept from the experiment
Centralizing model names made the April swap small. The code recorded two model constants changing, plus three files with hardcoded model strings. That is still a useful lesson from the original experiment.
The follow-up matters too. The April 23 warm-cache results put the small models much closer in latency than the first comparison suggested, and the project returned to Qwen. A model can win one quick test and still be the wrong choice for the routine job it will do every day.
The useful pattern for me is to give local models bounded work I can check. The earlier MacBook and iPhone experiment started with that question. This Mac Mini run pushed the size further, then the production setup became smaller again.
If you try a similar setup, keep a few real inputs with expected answers and measure them after each change. That gives the next model swap something concrete to beat.
For running AI automations and classification I use make.com rather than a local setup since it's - in theory at least - always-on. The tasks and pipelines I run there are lightweight enough that in the most cases no extensive context is needed to complete them: https://metacircuits.substack.com/p/how-i-built-my-second-brain-in-3
I'm paying roughly USD 10 per month in API credits for classification, analysis, and summarization, but don't expect to be running this setup indefinitely so I don't see the need to switch for the moment.
Very interesting! There's probably a market for startups who can build this kind of offering for businesses and help them save $$$. It addresses a key shortcoming of Claude and big LLMs: they're optimized for heavy duty stuff but charge the same price for easy task. The delegation model is elegant. Ideally, the app on your PC would decide which model to use (local vs cloud) and do all the fancy optimization for you (similar to your approach.